AI Feature 2
| Self-Attention in a Transformer Layer |
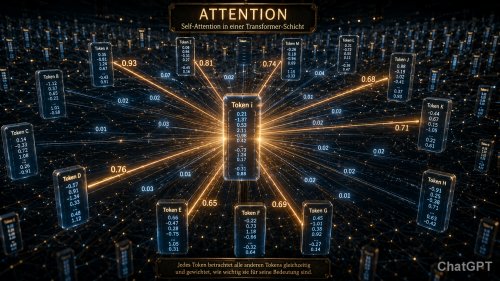
| Each token considers all other tokens simultaneously and determines how important they are to its
meaning. |
What exactly is 'Attention'? This term is quite important in the context of transformer models. Where is it primarily used in these?
As mentioned in AI Feature 1, we are currently in a language model. Understanding words and sentences may not be something a computer-based system is particularly good at. It focuses more on how the meaning of
one word affects the others, for example, within a sentence.
This relationship is important, and changing a word or part of a word can affect the meaning of all the other words. It makes a difference whether you have ChatGPT translate just one sentence, a segment of text, or an
entire chapter.
Even changing a single sentence in the first chapter of a book can affect the entire story, depending on the scope of the current context. Attention calculates, for each token, which other tokens are important for its current
meaning and how heavily they should be weighted.
As mentioned in the previous chapter, this involves converting text into tokens, which seem strangely unfamiliar to us. We won't explain those here either, nor will we explain the specifications of these with dimensions.
Create a sentence in your head, including its breakdown into tokens, which can consist of one or more letters or an entire word. And beneath each token is an incredibly long column of numbers whose origin we also don't
understand.
To the user, they appear suddenly; in fact, they were generated beforehand using a process known as embedding. They can apparently even be negative or have decimal places, but as far as we understand, they are
merely placeholders for the correct mathematical calculation to some other tokens.
| The numbers seem completely arbitrary. In fact, they were adjusted during training
so that similar meanings would later be assigned to similar vectors. |
Crucially, the conversion into these lists of numbers (vectors) means that the letters from which the token was formed have disappeared. It is simply assigned a number via a huge token list and is tracked accordingly.
By the way, the longer the transformation takes, the more the individual values within the lists of numbers change, and you would be able to recognize similarities when the values are particularly close, and, of course,
significant differences when the values are far apart.
We have long since moved beyond simply handling, for example, a sentence entered at Prompt. The books I once read no longer exist as texts, but only as knowledge stored in billions of weights in the neural network.
| It's also important to mention that we have long since moved from sequential processing of an entire
sentence to parallel processing, which, although it requires much more computing power, also results in a huge gain in speed. |
During the calculation, the vectors of the tokens change constantly. The parameters of the neural network remain unchanged and are used solely to calculate these changes. Complex mathematical operations that also
take into account the relationships between tokens in the network.
In the past, words were processed one after another. That's why it was hard for one word to remember another that might have come a hundred words earlier. Attention solves this problem. Each token
can directly examine any other token and determine how important it is to its current meaning. This makes it possible to identify connections even between things that are very far apart.
We've now more or less established how to determine the proximity of tokens, but we haven't yet determined the order. That is why the vectors also contain information about the original order of the
tokens. These positional datails are by no means random, unlike many other numbers in the vector. They are, therefore, explicitly not arbitrary.
|